September 16, 2026
How to seamlessly gather enough data from the field to shift from lagging to leading risk insights.
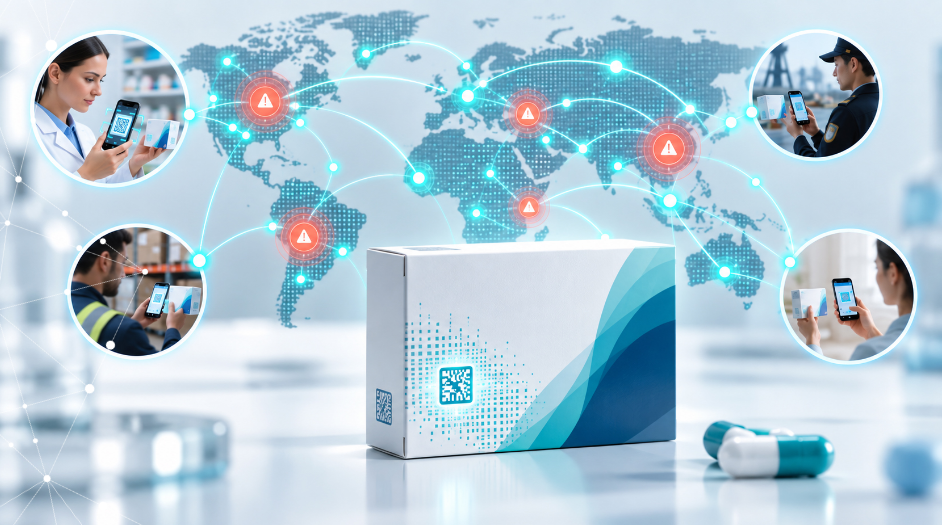
Today, product authenticity checks happen sporadically at formal checkpoints across vast markets: during a wholesaler's intake, a field investigator's visual inspection, or a customs stop. The data is real, but it's not at sufficient speed or scale to generate leading, actionable insights into emerging counterfeiting and diversion risks. By enabling anyone with a smartphone to scan and authenticate products carrying Digimarc's covert digital identifiers, brands can capture more data across markets for predictive risk intelligence.
Ask a brand protection team how they find out about counterfeiting, and the honest answer is usually some version of: we find out long after the fact. After a patient reports an adverse event. After a wholesaler's spot-check turns something up. After INTERPOL or the FDA issues a public alert. Every one of those findings is a real and useful signal — and every one of them arrives after the counterfeit has already been circulating for weeks or even months.
This is not a failure of any individual team. It's just how counterfeit-related data gets collected today. Verification happens at a handful of formal checkpoints such as a wholesaler's intake scan, a field investigator's visual inspection, or a customs stop — and those checkpoints are sparse relative to the size of a global supply chain. A brand might have a few dozen trained field agents covering markets where millions of units move every week.
The problem is that the data is real, but it's a thin sample, collected slowly, mostly after something has already gone wrong. It’s captured in forms and often emailed spreadsheets and reports. It’s all scattered, hard to aggregate, and not at sufficient scale to be useful for generating leading, actionable insights from.
As sophisticated counterfeiters get better at producing fakes that are nearly impossible to discern from real products, right down to cloned serial numbers, what does it take to see a counterfeiting problem emerging, rather than reading about it after the fact, so brand teams can proactively address it?
Think about how weather forecasting works. A handful of expensive, precisely calibrated weather stations can tell you the exact temperature at a few dozen points on a map. That's accurate, but it's not a forecast — you can't see a storm system forming from a dozen data points spread across a continent. What makes forecasting possible is sufficient data density, meaning a large volume of authentication scans collected across many locations, users, products, and time periods to generate enough data points to identify emerging counterfeit or diversion patterns early. Think thousands of readings, many of them individually low precision, but aggregated into a broader pattern that reveals what’s emerging before the storm fully arrives.
Brand protection against counterfeiting has been operating on the weather-station model: a small number of highly trained, highly precise checkpoints. This approach is good at confirming a specific counterfeit once you already suspect one — that is, if it can discern highly realistic and even serialized fakes. It's bad at spotting a pattern early, because early patterns are, by definition, faint — a few anomalies scattered across a wide area, not yet concentrated enough for any single checkpoint to notice.
To catch a pattern while it's still faint, you don't need fewer, more precise data points. You need many more of them.
This is the shift that Digimarc’s covert digital identifiers make possible because:
As you can see, data is no longer collected by just the trained field agent with pictures of what “real” looks like or specialized equipment. It's the pharmacist scanning a package at dispense. It's the distributor checking a pallet at intake. It’s the brand inspector in a store. It's a patient or a channel partner using a verification app. Regardless of who takes it, every scan becomes a sensor in the network, not a bottleneck waiting for a specialist to arrive.
Crowd-sourced at scale — that's a fundamentally different kind of dataset than a handful of field-agent reports. Instead of a sparse set of high-confidence checkpoints, you get a dense, continuously updating stream of verification events across markets, distributors, and time. This is the raw material that can be analyzed to actually see a pattern take shape instead of reading about it after it’s already become a headline.
At Digimarc, a positive scan happens when our Validate app successfully detects the presence of a Digimarc digital identifier during authentication, evidence that the product is authentic. A negative or “failed” scan occurs when the Validate app does not detect the presence of a Digimarc digital identifier during authentication. This indicates that the product lacks evidence of authenticity.
When you’re dealing with large volumes of crowd-sourced data, even a package scan that doesn't detect a digital identifier is not a “null” result. It's a signal, and a valuable one.
Why? Because if a genuine product reliably carries the covert digital identifier and a scan comes back empty, one of two things is true: either the reader failed for a mundane reason (such as insufficient lighting or poor print production QA), or the package in someone's hand didn't come from an authentic printing run. At the level of a single scan, you can't always tell which. But at the level of thousands of scans, you can. A random scatter of failed reads — or even the mere absence of scans — across markets looks like noise. A cluster of failed reads concentrated in one region, one distributor, or one product line over a short window looks like something else entirely: the early shape of a counterfeiting or diversion problem, visible before a single confirmed counterfeit has been physically recovered and analyzed.
The key takeaway is this: every scan carries information, whether it succeeds or not. A successful scan confirms the presence of a Digimarc digital identifier. A failed scan, aggregated with others, can flag where a problem is forming. Treating "failed" scans as noise to be filtered out — rather than as the earliest available signal — is leaving the most predictive part of the dataset on the table.
This same density of data does something else brand teams consistently say they lack: early visibility into diversion, not just counterfeiting. A product that's genuinely authentic but has been diverted from its intended market (i.e., sold outside its authorized channel, repackaged, or routed around contracted pricing and distribution agreements) won't show up as a "counterfeit" in the traditional sense, because it is real product. But it will show up in scan-location data as a mismatch: a genuine watermark, verified in a place or a channel it was never supposed to be.
Crowd-sourced verification data makes this problem visible in a way that occasional field inspections structurally can't, because diversion patterns depend on seeing where things happen at scale, not confirming any single instance.
Aggregated centrally, this data can be analyzed continuously by your back-office analytics and AI layer. This is how all those individual scans — successful and failed alike — become something your brand protection team can act on, such as:
While it’s true that none of this replaces deeper field investigations or serialization compliance, the seamless mass scanning of packaging for covert digital identifiers sharpens both. For example, a field team can point to a new cluster that the data has started to flag, rather than overlooking an emerging risk. And a serialization audit paired with pattern-level scan intelligence can distinguish "this credential is technically valid" from "this credential is appearing in a place that should worry us."
The teams getting ahead of counterfeiting in 2026 aren't the ones with the most field agents. They're the ones who've turned every point of contact with their product — pharmacist, distributor, patient, investigator — into a source of intelligence, and who treat a failed scan with the same seriousness as a successful one.
Only covert digital identifiers embedded into packaging during authentic, brand-authorized production lines can deliver this kind of distributed, predictive intelligence without unsightly codes, electronic tags, or significant changes to existing production processes. And today, it’s vital to closing the gap that serialization and occasional inspections leave open, as explored in our latest paper, The Detection Gap: How Pharma Brand Protection Quietly Became a Liability Question.
Share this Blog